• Validation study
  • The in-house build test

Elaiia AI twins vs. a standard LLM – benchmark against the European Social Survey

Same 15 European Social Survey questions, same scales, same public ground truth. Elaiia twins: 1.5% mean deviation. A standard LLM role-playing 100 respondents: 14.0%.

Abstract illustration: particles following a precise luminous curve beside loosely scattered particles – AI twins versus a standard LLM

Elaiia calibrated twins

1.5%

standard model, 100 personas

14.0%

standard model, direct estimate

11.0%

Mean deviation from the real Swiss population across all 15 variables.

Accuracy holds only where the answer has already been published

Line chart: mean deviation from the European Social Survey (Switzerland, Round 11). Standard LLM 6.5% on 9 items with a published statistic, 25.2% on 6 personal-value items; Elaiia calibrated twins 1.5% on both.
Split the benchmark by whether a published statistic for the item plausibly exists.

The ranking insight teams act on does not survive
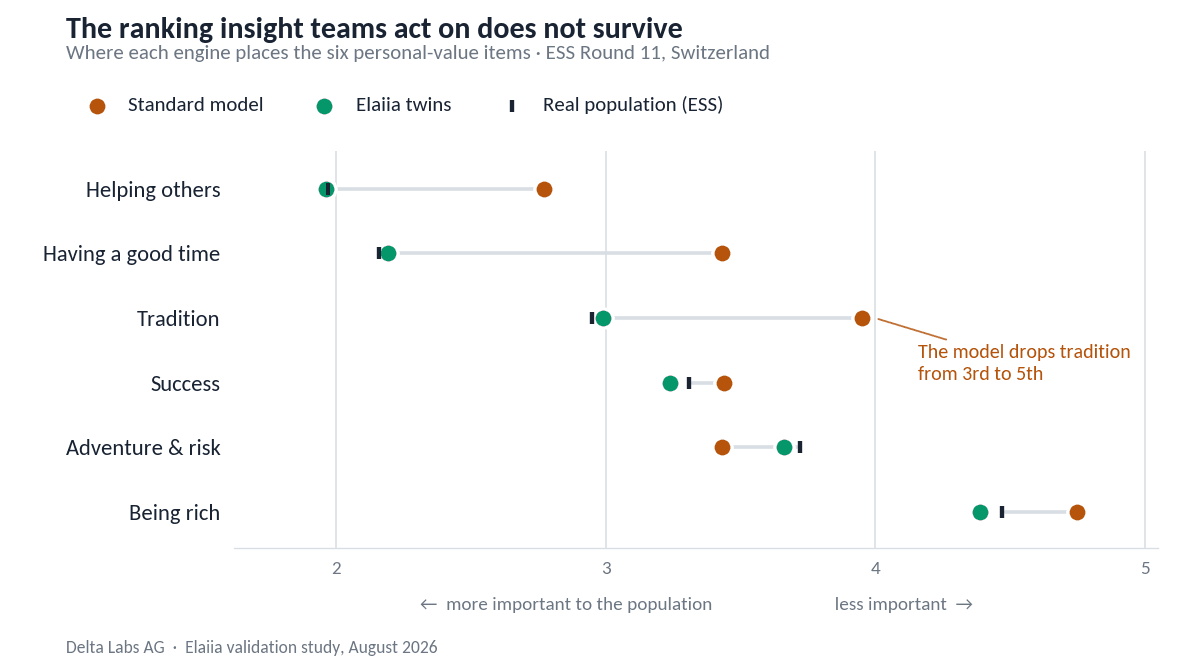
Chart: value ranking of the Swiss population, ESS vs. Elaiia twins vs. a standard LLM.
On these scales a lower mean means the value matters more to the population.

Every objection we could raise against ourselves, granted in full

Chart: five hostile variants of the benchmark with contested items removed, Elaiia twins vs. a standard LLM.
Five hostile variants of the same benchmark, each with contested items removed.

Value hierarchy

Dot chart: mean position on the 1–6 importance scale for six values – ESS 11 real Swiss respondents, Elaiia AI twins and standard GPT personas; span of the value hierarchy ESS 2.50, twins 2.43, GPT 1.98.
From the validation deck, p. 8

Headline result

Validation deck page 4: mean deviation from ESS – Elaiia AI twins 1.5%, GPT 100 personas 14.0%, GPT direct estimate 11.0%; twins’ accuracy advantage 9.4×.
From the validation deck, p. 4

At a glance

StudyValidation study
BenchmarkEuropean Social Survey, Switzerland (Round 11)
Ground truthn = 1,384
Questions15, same scales
Elaiia twins1.5% mean deviation

Full validation report available on request.

Articles

Read the thinking behind the work.

Abstract illustration: particles collapsed into one narrow column beside a diverse, calibrated population

8 MIN READ

Why a very good language model still gets your population wrong

A like-for-like test of calibrated AI twins against a standard large language model, on a public benchmark nobody involved controls.

Read
Abstract illustration: a layered dark foundation with a glowing data core and calibrated blocks above

7 MIN READ

Why can’t we just build this ourselves?

The objection is framed as a capability question. It is not one. Three requirements decide whether a synthetic population can be trusted – and none of them is a modelling problem.

Read
Abstract illustration: a package on a measuring platform verified by a thin violet beam

4 MIN READ

Fast is the easy part. Right is the question.

How we verify that AI twins are accurate: a practical packaging case.

Read
Abstract illustration: a glass lens revealing a glowing violet structure in a vast network

4 MIN READ

The Real AI Disruption in B2B Marketing Isn’t Creative: It’s Diagnosis

B2B decision-makers are the most strategic audience in marketing and the least researchable. AI changes which part of the job is the bottleneck.

Read
Abstract illustration: insight particles flowing upward through three layers – insights, strategy, tactics

3 MIN READ

Insights → Strategy → Tactics: Why Most Marketing Starts at the Wrong End

Most teams start with tactics. Insight first changes everything downstream.

Read
Abstract illustration: one luminous shape chosen from a vast field of particles

3 MIN READ

Why Taste (= Market Research) Is THE Competitive Advantage in the AI Era

When execution becomes abundant, the scarce skill is knowing what your customers will choose.

Read
Elaiia

FROM ELAIIA ACADEMY

Stay close to what we’re learning.

New case studies, validation studies, articles and Forum insights from Elaiia Academy. Monthly, no more.